Summary
While advances in vision-language-action models (VLAs) have introduced robot policies that are both generalizable and semantically grounded, these models mainly rely on vision-based perception. Vision alone, however, cannot capture the complex interaction dynamics that occur during contact-rich manipulation, including contact forces, surface friction, compliance, and shear. Recent attempts to integrate tactile signals into VLA models often increase complexity through token concatenation or large-scale pretraining, yet the heavy computational demands of behaviour models necessitate lightweight fusion strategies.
We propose TacFiLM to address these challenges, a lightweight modality-fusion approach that integrates visual-tactile signals into vision-language-action (VLA) models. Our approach outlines a post-training finetuning approach that conditions intermediate visual features on pretrained tactile representations using featurewise linear modulation (FiLM).
Experimental results on insertion and drawer opening tasks demonstrate consistent improvements in success rate, direct task performance, completion time, and force stability across both in-distribution and out-of-distribution tasks. Together, these results support our method as an effective approach to integrating tactile signals into VLA models, improving contact-rich manipulation behaviours.
TLDR
Our main contributions are summarized as follows:
- TacFiLM, a novel lightweight modality fusion approach that integrates tactile signals through image conditioning.
- Comprehensive experiments showing that TacFiLM improves success rates by up to 50% with shorter episodes and reduced contact forces compared to concatenation and cross-attention-based fusion
- An investigation of the use of pretrained tactile encoders such as Sparsh and T3 in fusing tactile signals into VLA models.
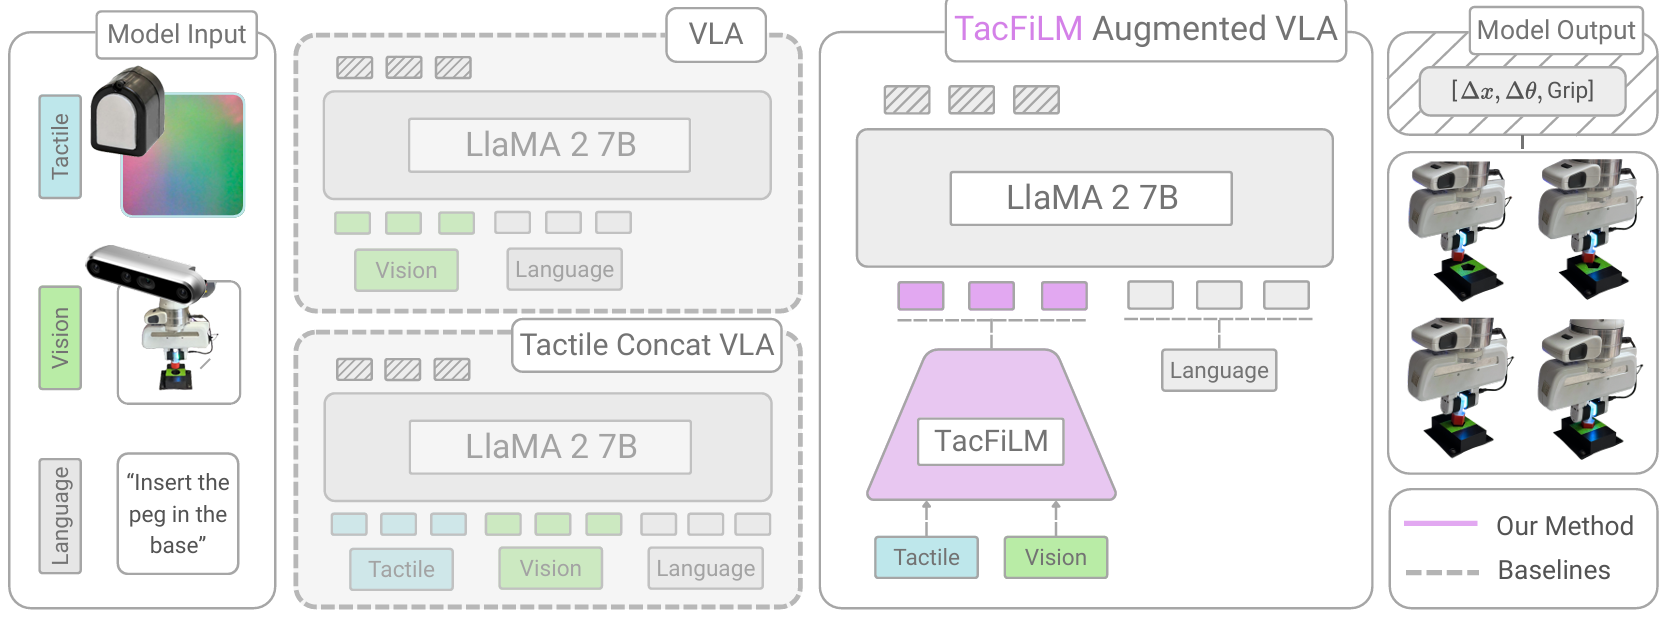
TacFiLM Overview. The left panel shows the model inputs, including tactile, visual, and language modalities. In grey, baseline approaches. To the right, we show our proposed TacFiLM-augmented VLA. The rightmost boxes show model outputs and rollouts.
TacFiLM: conditioning vision on touch
TacFiLM integrates touch through feature-wise linear modulation (FiLM). A tactile encoder reads the contact image and predicts per-channel scale (gamma) and shift (beta) values; each visual feature is then scaled and offset accordingly. In effect, touch is allowed to reweight and bias what vision sees, amplifying what matters at contact and damping the rest, all without lengthening the sequence the transformer processes. Because we condition rather than re-architect, the OpenVLA-OFT backbone stays intact, latency barely moves, and adaptation is fast and data-efficient. We also reuse pretrained tactile encoders such as T3 and Sparsh, so TacFiLM benefits from tactile pretraining the same way the VLA already benefits from vision-language pretraining.
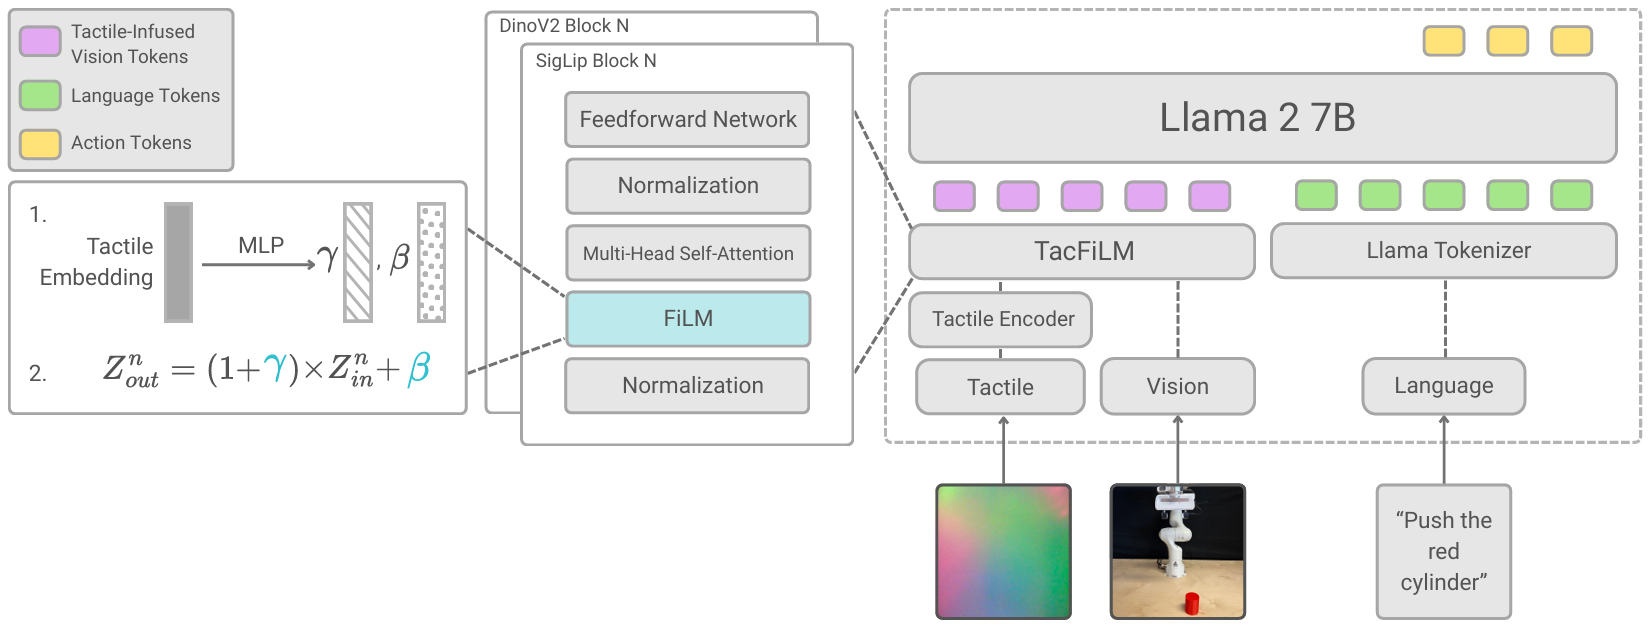
TacFiLM architecture. A pretrained tactile encoder maps the contact image to FiLM parameters that modulate the visual features inside the VLA backbone, leaving the vision-language pathway and the action decoder otherwise untouched.
Tasks
Task definitions. Insertion tasks differ in peg or connector shape and clearance but share the goal of successful insertion. Open-drawer consists of hooking the gripper under the drawer and pulling it open.
Results
We test TacFiLM on contact-rich insertion and opening tasks with a Franka Panda arm and a DIGIT sensor, the regime where vision-only policies struggle most. Conditioning on touch increases both success rate and force stability, with the largest gains on tight-tolerance insertions where feedback carries the most information. Please see paper for full results including both the ablation study and tactile representation analysis.

Insertions task ID results. Real-robot insertion experiments with a Franka Panda and a DIGIT tactile sensor. TacFiLM improves success rates and force stability over vision-only baselines, with the biggest improvements on tight-tolerance insertions.
In-distribution results (avg. across 4 tasks)
| Method | Success (%) | Direct (%) | Max Force (N) | Time (s) |
|---|---|---|---|---|
| OpenVLA-OFT | 58.00 | 12.38 | 14.94 ± 9.16 | 126.7 ± 51.34 |
| TactileConcat | 64.76 | 10.48 | 10.27 ± 4.12 | 113.04 ± 52.31 |
| Cross-Attn | 48.00 | 12.00 | 13.43 ± 12.62 | 149.92 ± 39.01 |
| TacFiLM (ours) | 86.67 | 37.14 | 8.65 ± 3.80 | 81.72 ± 38.00 |
Out-of-distribution results (avg. across 5 tasks)
| Method | Success (%) | Direct (%) | Max Force (N) | Time (s) |
|---|---|---|---|---|
| OpenVLA-OFT | 54.67 | 0.00 | 22.46 ± 15.75 | 89.48 ± 46.05 |
| TactileConcat | 73.33 | 8.00 | 6.47 ± 10.54 | 105.79 ± 43.16 |
| Cross-Attn | 49.33 | 5.33 | 19.27 ± 14.62 | 149.77 ± 33.72 |
| TacFiLM (ours) | 86.67 | 29.33 | 8.40 ± 4.71 | 87.84 ± 42.69 |
Code and data will be released soon, watch this page. More media and qualitative rollouts will be added here as they become available.
Citation
@article{morissette2026tactile,
  title   = {Tactile Modality Fusion for Vision-Language-Action Models},
  author  = {Morissette, Charlotte and Abyaneh, Amin and Chang, Wei-Di and
             Houssaini, Anas and Meger, David and Lin, Hsiu-Chin and
             Tremblay, Jonathan and Dudek, Gregory},
  journal = {arXiv preprint arXiv:2603.14604},
  year    = {2026}
}